 [ BESMALA ]
Machine Learning · 1 study sheet
Batch 01
Study the machine-learning workflow, data splits, generalization, feature selection, clustering, dimensionality reduction, and evaluation metrics.
↑ Contents / Machine Learning
Machine Learning Fundamentals
1The ML workflow
.fit()?Intuition
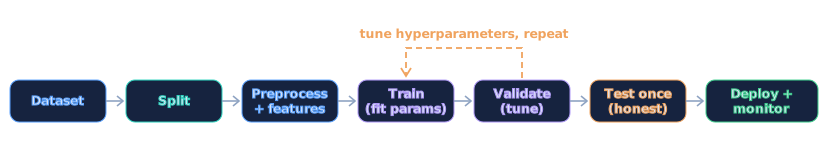
ML is a disciplined loop, not a single action: get data → carve out untouched evaluation data → prepare features → fit a model → measure honestly → improve → measure once more on the untouched data. Most real project time is spent on the data and the evaluation, not the model.
Technical — the stages
- Collect & split — set aside evaluation data before making any modeling choices (§3).
- Preprocess & engineer features — scaling, encoding, missing values. Every transformation’s parameters must be learned on training data only.
- Train — the learning algorithm adjusts the model’s parameters (weights) to minimize a loss.
- Validate — compare candidate models and hyperparameters (values you choose, not learn — §7).
- Test — one final unbiased estimate on data that influenced zero decisions.
- Deploy & monitor — real data drifts; performance decays without retraining (Chapter 5).
Common misconception
“The modeling is the hard part.” In practice, projects fail most often at evaluation discipline — leaky splits (§3) and tuning on the test set produce beautiful numbers that collapse in production.
Knowledge check
Why must the test set be used only once? Answer: every time you look at test performance and make a decision based on it (keep the model, change a hyperparameter, drop a feature), information flows from the test set into your choices — the estimate stops being unbiased. Repeated testing quietly turns the test set into a second validation set.
2Four ways a model can learn
| Paradigm | Training signal | Typical tasks | Connection to our GPT |
|---|---|---|---|
| Supervised | Explicit pairs (input → correct output) | Spam detection, price prediction, image labels | — |
| Unsupervised | None — find structure in inputs | Clustering customers, dimensionality reduction (PCA) | — |
| Self-supervised | Labels generated from the data itself | Next-token prediction, masked-word filling | ← pretraining is exactly this: the “label” is the next token in the stream (our y = x shifted by 1) |
| Reinforcement | Rewards from actions in an environment | Game playing, robotics, RLHF fine-tuning | Stage 3 of ChatGPT-style training |
Technical
The paradigms differ only in where the error signal comes from. Supervised learning compares the prediction to a human-provided target. Self-supervised supervision is automatic: hide part of the input, make the model reconstruct it — the data is its own teacher at massive scale, which is why LLMs can be trained on trillions of tokens without human labeling.
Common misconception
“Unsupervised learning needs no data preparation.” It receives no labels, but still suffers from every data-quality problem — and there is often no obvious metric to tell you the clustering is “right,” which makes evaluation harder, not easier.
Knowledge check
GPT pretraining predicts the next token in raw text. Which paradigm is that? Answer: self-supervised — targets are extracted from the data itself, no human annotation needed. (Fine-tuning on human-written instruction/answer pairs is supervised.)
3Features, labels, and the three datasets
Intuition
Grading a student on questions they already saw in class measures memorization, not understanding. You need questions the student has never seen. That is the entire point of splitting data.
Technical — vocabulary
- Example (row): one observation. Feature (x): an input attribute. Label (y): the value to predict.
- Training set (~70%) — the algorithm adjusts parameters here.
- Validation set (~15%) — used to compare models, pick hyperparameters, choose the epoch to stop at.
- Test set (~15%) — touched once, at the end. Proportions are conventions, not laws; with little data, use cross-validation instead (§7).
Common misconception — data leakage
Leakage = information from outside the training window sneaking into training, inflating scores that won’t survive contact with real data. Classic forms:
- Preprocessing leakage: computing scaling/normalization statistics on the full dataset before splitting. Fix: fit the scaler on train only, then transform val/test.
- Target leakage: a feature that could only be known after the outcome (e.g., “discharge medication” predicting hospital readmission — it implies the patient was discharged).
- Temporal leakage: random splitting of time-series data lets the model “see the future.” Fix: split by time.
- Duplicates: near-identical rows spanning train and test.
Knowledge check
You standardize features using the mean/variance of the whole dataset, then split 70/15/15. What exactly is wrong? Answer: preprocessing leakage — test-set statistics influenced the training representation. The test set is no longer untouched. Correct order: split first, fit the scaler on train only, apply it to val/test.
4Underfitting, overfitting, bias & variance
Intuition
A model must balance two failure modes: being too simple to capture the real pattern (underfitting) and being so flexible it fits the noise (overfitting). The noise is different in every sample — a model that memorizes it has learned something that won’t transfer.
Technical — bias & variance
- Bias = systematic error from a too-rigid hypothesis class (the straight line can’t bend). High bias → underfitting.
- Variance = sensitivity to the particular training sample — retrain on a different sample and the wiggly line changes wildly. High variance → overfitting.
- Expected test error ≈ bias² + variance + irreducible noise. Decreasing one typically raises the other — the bias–variance tradeoff, controlled by model capacity and regularization (§5).
Simplification: the classic tradeoff story is a useful mental model, but modern heavily over-parameterized networks can have low test error despite near-zero training error (“double descent”). The diagnosis via train vs validation curves below stays valid regardless.
| Train score | Validation score | Diagnosis | Typical fixes |
|---|---|---|---|
| Low | Low | Underfitting (high bias) | Bigger/expressive model, better features, train longer, lower regularization |
| High | Low | Overfitting (high variance) | More data, regularization (§5), simpler model, data augmentation, early stopping |
| Low | High | Suspicious — check for leakage or a broken pipeline | Audit the split and preprocessing order |
| High | High | Healthy | Ship it — after one honest test pass |
Common misconception
“Overfitting means the model memorized — always catastrophic.” Memorization and generalization coexist in large models; the operative question is always validation/test performance, not whether any memorization occurred.
Knowledge check
Train accuracy 99%, validation accuracy 82%. Diagnosis and two concrete fixes? Answer: overfitting. Fixes: add regularization (L2/weight decay, dropout for nets) and increase training data or augmentation; alternatively reduce model capacity or use early stopping at the validation minimum.
5Regularization & generalization
Intuition
Regularization adds a price for complexity. The optimizer must now earn every unit of model wiggliness — so it keeps only the structure that genuinely reduces error.
Technical
Generalization = performance on unseen data; the train–validation gap measures it. Regularized objective (add a penalty to the loss):
Jreg(w) = Loss(w) + λ Σ wi2 (L2 / ridge / weight decay)
Jreg(w) = Loss(w) + λ Σ |wi| (L1 / lasso)
- L2 shrinks all weights toward zero — smoother functions, no exact zeros. Default in deep learning (“weight decay”).
- L1 drives some weights to exactly zero → feature selection / sparse models.
- Early stopping — stop at the validation-loss minimum (the sweet spot in §4’s plot).
- Dropout (deep nets) — randomly disable neurons during training so no single path is relied upon.
- Data augmentation — enlarges effective data; the most “physical” regularizer of all.
λ is a hyperparameter: too small → overfit; too large → underfit. Choose it on validation data only.
Common misconception
“Regularization is a classical-ML thing.” Deep learning is saturated with it: weight decay, dropout, augmentation, early stopping, even label smoothing. The knobs have different names; the principle is identical.
Knowledge check
You crank λ to 106. What happens to train and validation error, and why? Answer: both rise — the weights are crushed toward zero, the model can barely fit anything: heavy underfitting. λ trades bias for variance; its value is a validation-set decision.
6Classification & regression metrics
Intuition — the accuracy trap
Fraud is 0.5% of transactions. A model that predicts “not fraud” always scores 99.5% accuracy and catches zero fraudsters. Accuracy hides what you care about when classes are imbalanced or error costs differ.
Technical — the confusion matrix
Precision = TP / (TP + FP) · “when I alarm, how often am I right?”
Recall = TP / (TP + FN) · “of all real cases, how many did I catch?”
F1 = 2·P·R / (P + R) · harmonic mean — punishes imbalance between P and R
Choosing: cancer screening / fraud → favor recall (missed cases are costly); spam filter / auto-moderation → favor precision (false alarms erode trust); balanced costs → accuracy or F1. ROC-AUC summarizes ranking quality across thresholds — useful, but misleading on extreme imbalance.
Technical — regression metrics
MAE = (1/n) Σ |yi − ŷi| · robust to outliers, same units as y
MSE = (1/n) Σ (yi − ŷi)2 · punishes large errors hard; RMSE = √MSE restores units
R² = 1 − SSres / SStot · variance explained vs. always predicting the mean (can be negative!)
Rule of thumb: outliers matter → MAE; large errors are disproportionately costly → RMSE; always report at least two metrics and the residual distribution.
Common misconception
“F1 is the best single number.” F1 treats precision and recall as equally important — they rarely are. If a missed tumor costs 100× a false alarm, no scalar metric encodes that; you set the decision threshold (or metric weighting) explicitly.
Knowledge check
Model A: precision 0.95, recall 0.50. Model B: precision 0.70, recall 0.70. Which for a medical screening test? Answer: screening tolerates false alarms (confirmed by later tests) but hates missed cases → recall dominates → Model B (or lower A’s decision threshold). This is why you must know the cost structure before choosing a metric.
7Cross-validation & hyperparameter tuning
Intuition
Instead of trusting one lucky (or unlucky) split, rotate the validation role through the data and average. Every example gets used for both training and validation — just never both at once.
Technical — k-fold CV (k = 5)
Parameter vs hyperparameter: parameters (weights) are learned by the optimizer inside a fold; hyperparameters (λ, tree depth, learning rate, k in k-NN) are chosen by you across folds.
Tuning strategies: grid search (try the Cartesian product — explodes fast) vs random search (sample configurations — usually finds good regions with far fewer runs). Nested CV is the rigorous version where tuning happens strictly inside training folds. Whatever the strategy: any feature selection or preprocessing must live inside each fold, or you leak (§3).
Common misconception
“CV replaces the test set.” No — CV gives a better validation estimate for model selection. You still keep a final untouched test set for the one honest measurement.
Knowledge check
Your team runs feature selection on the full dataset, then 5-fold CV on the survivors. Why is the CV score optimistic? Answer: the features were chosen using information from all rows — including the fold that acts as “validation.” The folds are no longer independent of the selection step; the fix is performing selection inside each fold’s training portion only.
8Knowledge check — the quiz
Attempt each before expanding. Explanations reference the sections.
Q1 — Why is tuning on the test set a methodological crime?
Every decision informed by the test set transfers test information into your choices, so the final “unbiased” number no longer estimates unseen-data performance. Test = final exam; you don’t get retakes that mean anything. (§1, §3)
Q2 — Train loss 0.03, validation loss 0.9 and rising. What, and two fixes?
Overfitting (high variance). Fixes: regularization (L2/dropout/early stopping) and more effective data (collection or augmentation); or reduce capacity. (§4, §5)
Q3 — Fraud rate 0.5%. Detector reports 99.5% accuracy and recall 0. What’s happening?
It predicts “not fraud” for everything — the accuracy paradox under extreme imbalance. Judge it by precision/recall on the fraud class, or PR-AUC. (§6)
Q4 — Next-token prediction on raw web text is which paradigm, and where do the labels come from?
Self-supervised: the label for position t is the token at t+1 — extracted mechanically from the corpus.
This is exactly the y = x shifted by one batching in our GPT repo. (§2)
Q5 — Why must cross-validation include the preprocessing inside each fold?
Scalers, imputers, and feature selectors learn statistics from data. Fitting them on all data before folding lets validation-fold statistics leak into training. Fit on each fold’s train portion only. (§3, §7)
9Exercise — honest evaluation from scratch
Implementation challenge
Build k-fold evaluation with your own metric implementations, then verify against scikit-learn. This exercise encodes §3, §6 and §7 into muscle memory.
# ml_exercise.py — numpy + scikit-learn only. pip install numpy scikit-learn
import numpy as np
from sklearn.datasets import load_breast_cancer   # real dataset, bundled offline
from sklearn.linear_model import LogisticRegression
from sklearn.preprocessing import StandardScaler

X, y = load_breast_cancer(return_X_y=True)

def kfold_indices(n, k, seed=0):
    """Return list of (train_idx, val_idx) for k-fold CV."""
    rng = np.random.default_rng(seed)
    folds = np.array_split(rng.permutation(n), k)
    for i in range(k):
        val = folds[i]
        train = np.concatenate([folds[j] for j in range(k) if j != i])
        yield train, val

def prf(y_true, y_pred):
    """Precision, recall, F1, accuracy — from the confusion matrix."""
    tp = np.sum((y_true == 1) & (y_pred == 1))
    fp = np.sum((y_true == 0) & (y_pred == 1))
    fn = np.sum((y_true == 1) & (y_pred == 0))
    precision = tp / (tp + fp)  if (tp + fp) else 0.0
    recall    = tp / (tp + fn)  if (tp + fn) else 0.0
    f1 = 2 * precision * recall / (precision + recall) if (precision + recall) else 0.0
    acc = np.mean(y_true == y_pred)
    return precision, recall, f1, acc

scores = []
for tr, va in kfold_indices(len(y), 5):
    scaler = StandardScaler().fit(X[tr])          # fit on TRAIN FOLD ONLY — §3!
    model  = LogisticRegression(max_iter=5000).fit(scaler.transform(X[tr]), y[tr])
    scores.append(prf(y[va], model.predict(scaler.transform(X[va]))))

m = np.mean(scores, axis=0); s = np.std(scores, axis=0)
print(f"precision {m[0]:.3f}±{s[0]:.3f}  recall {m[1]:.3f}±{s[1]:.3f}  "
      f"F1 {m[2]:.3f}±{s[2]:.3f}  acc {m[3]:.3f}±{s[3]:.3f}")

# Cross-check against scikit-learn (should match to ~1e-3):
from sklearn.model_selection import cross_validate
# ...compare your numbers with cross_validate(LogisticRegression(max_iter=5000),
#  StandardScaler().fit_transform(X), y, cv=5, scoring=["precision","recall","f1"])
# NOTE: fitting the scaler on ALL X here is the leakage version — expect slightly
# different (optimistic) numbers. The gap varies by dataset; the discipline matters.
Deliverables: (1) your metric function matching sklearn’s to ~1e-3; (2) a 3-sentence note on why the scaler is fit inside the loop; (3) stretch: add a deliberately leaky version (scaler fit on all X before splitting) and report the metric delta you observe.
10References
- scikit-learn User Guide — model selection & metrics: scikit-learn.org/stable/user_guide.html
- Goodfellow, Bengio, Courville — Deep Learning (MIT Press, 2016), ch. 5 “Machine Learning Basics”: deeplearningbook.org
- P. Domingos — “A Few Useful Things to Know About Machine Learning,” CACM 55(10), 2012: author’s page (PDF)
- Google ML Crash Course — guided practical: developers.google.com/machine-learning/crash-course
- StatQuest (J. Starmer) — bias/variance, ROC, regularization, explained visually: youtube.com/@statquest
These are stable, official or primary sources; links verified at time of writing. If one rots, search the title. Nothing on this sheet is a fabricated citation.
Progress checklist
Ticks persist in this browser only (localStorage).
Provenance: structured sheet from Batch 1 of the AI Learning Lab project — a personal study resource, not a claim of expertise. Verify specifics against the references before use in graded work.
Last reviewed: not yet — set this date after your first full pass.
The source material is preserved in full. Open the complete original HTML collection.